Yinming Huang 「黄音铭」
| Github |
Email |
Google Scholar |
|
I am a first-year Ph.D. student at Fudan University, jointly trained with Shanghai Innovation Institute, under the supervision of Prof. Zuxuan Wu. I also work closely with Shuyuan Tu. Prior to that, I received my B.Eng. degree in Artificial
Intelligence from Fudan University in 2026.
My research focuses on reinforcement learning for video generation and agentic visual generation. I am particularly interested in building generative models that learn from external feedback and developing agentic frameworks that enable them to adapt and improve over time through interaction.
Email: 26113050052 [AT] m.fudan.edu.cn
|
|
Education
Fudan University
B.Eng. in Artificial Intelligence
Sep. 2022 – Jun. 2026
Honors & Awards
- Outstanding Graduate of Fudan University, 2026
- First-Class Scholarship for Outstanding Undergraduate Students, Fudan University, 2023-2024
- First-Class Scholarship for Outstanding Undergraduate Students, Fudan University, 2022-2023
- First Prize in the Preliminary Round of the Chinese Mathematical Olympiad (2021)
|
Experience
2030 Lab, Yinwang Intelligent Technology Co., Ltd.
Research Intern
Dec. 2025 – Aug. 2026
University of California, San Diego (UCSD)
Exchange Student
Sep. 2024 – Dec. 2024
|
|
Prism: Dynamic Sparse Attention for Native 2K Joint Video-Audio Generation Model Training
Star
Shuyuan Tu*, Qi Tian*, Yinming Huang, Yue Wu, Xintong Han, Kaihang Pan, Weijie Kong, Jiangfeng Xiong, Jian-Wei Zhang, Zuxuan Wu, Yu-Gang Jiang
webpage |
abstract |
bibtex |
arXiv |
code |
model |
YouTube |
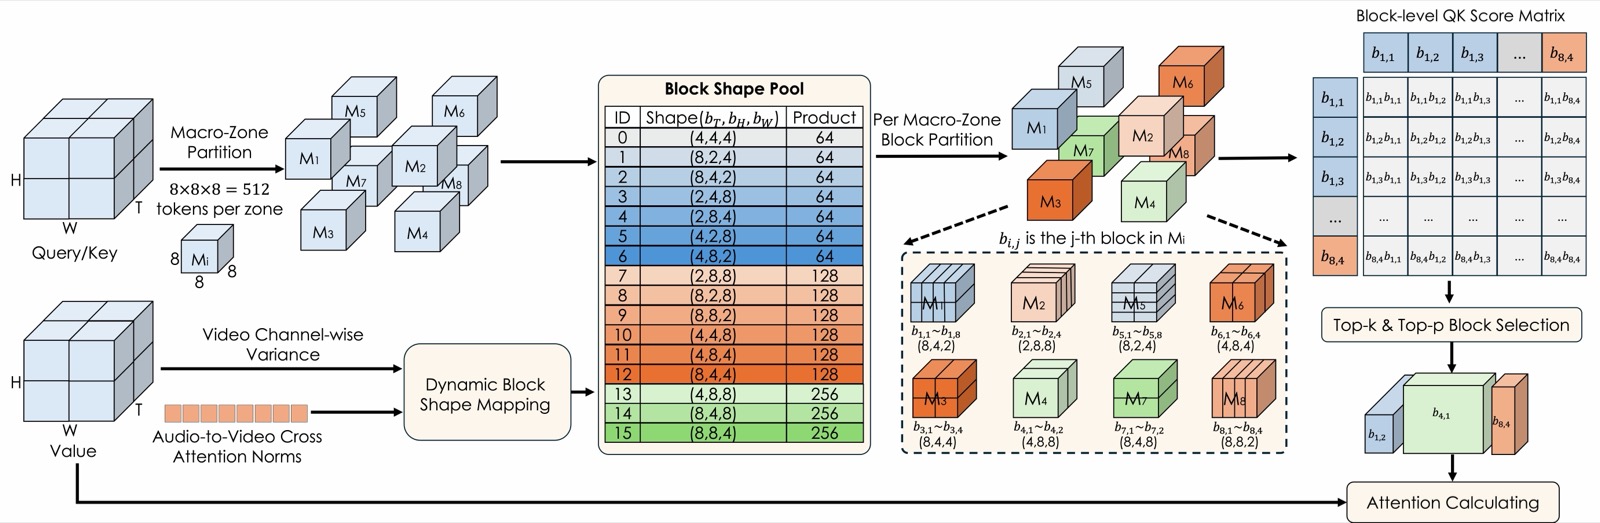
Natively training joint video-audio generation models at higher resolutions empowers them to learn richer visual details and sharper motion dynamics. However, full attention incurs quadratic cost and, as resolution increases, spreads attention over increasingly redundant tokens, diluting learning signals for informative content and disrupting pretrained priors. Existing sparse attention methods either target training-free acceleration or overlook the unique structure of joint video-audio data, where cross-modal interactions are inherently concentrated around sound-producing regions. To address this, we propose Prism, a dynamic sparse attention framework for natively training joint video-audio generation models at 2K. In particular, Prism organizes the token sequence into spatiotemporal macro-zones, enabling the attention structure to adapt to local content. For each zone, it estimates local information structure via video feature variance along the channel and feature norms from the audio-to-video cross-attention, jointly capturing how visual content varies directionally and how strongly audio influences each visual region. Based on these signals, Prism dynamically assigns a tailored block shape to each zone, applying finer partitioning along axes of rapid visual content variation and strong audio-visual coupling. This encourages tokens within each block to remain semantically coherent, allowing block-level features to capture both visual content and joint video-audio interaction patterns. Prism further adopts a hybrid block selection strategy to dynamically determine per-query sparsity. Experiments show that Prism achieves 2.5× training speedup compared to full attention, while surpassing it in generation quality.
@article{tu2026prism,
  title={Prism: Dynamic Sparse Attention for Native 2K Joint Video-Audio Generation Model Training},
  author={Tu, Shuyuan and Tian, Qi and Huang, Yinming and Wu, Yue and Han, Xintong and Pan, Kaihang and Kong, Weijie and Xiong, Jiangfeng and Zhang, Jian-Wei and Wu, Zuxuan and Jiang, Yu-Gang},
  journal={arXiv preprint arXiv:2610.05416},
  year={2026}
}
|
|
Agentic Visual Generation: From Generative Models to Agentic Control
Star
Yinming Huang*, Shuyuan Tu*, Xi Yan*, Jiahao Zhan, Zihan Yang, Zhen Xing, Hui Zhang, Tiehua Zhang, Yu-Gang Jiang, Zuxuan Wu
webpage |
abstract |
bibtex |
arXiv |
code |
机器之心 |
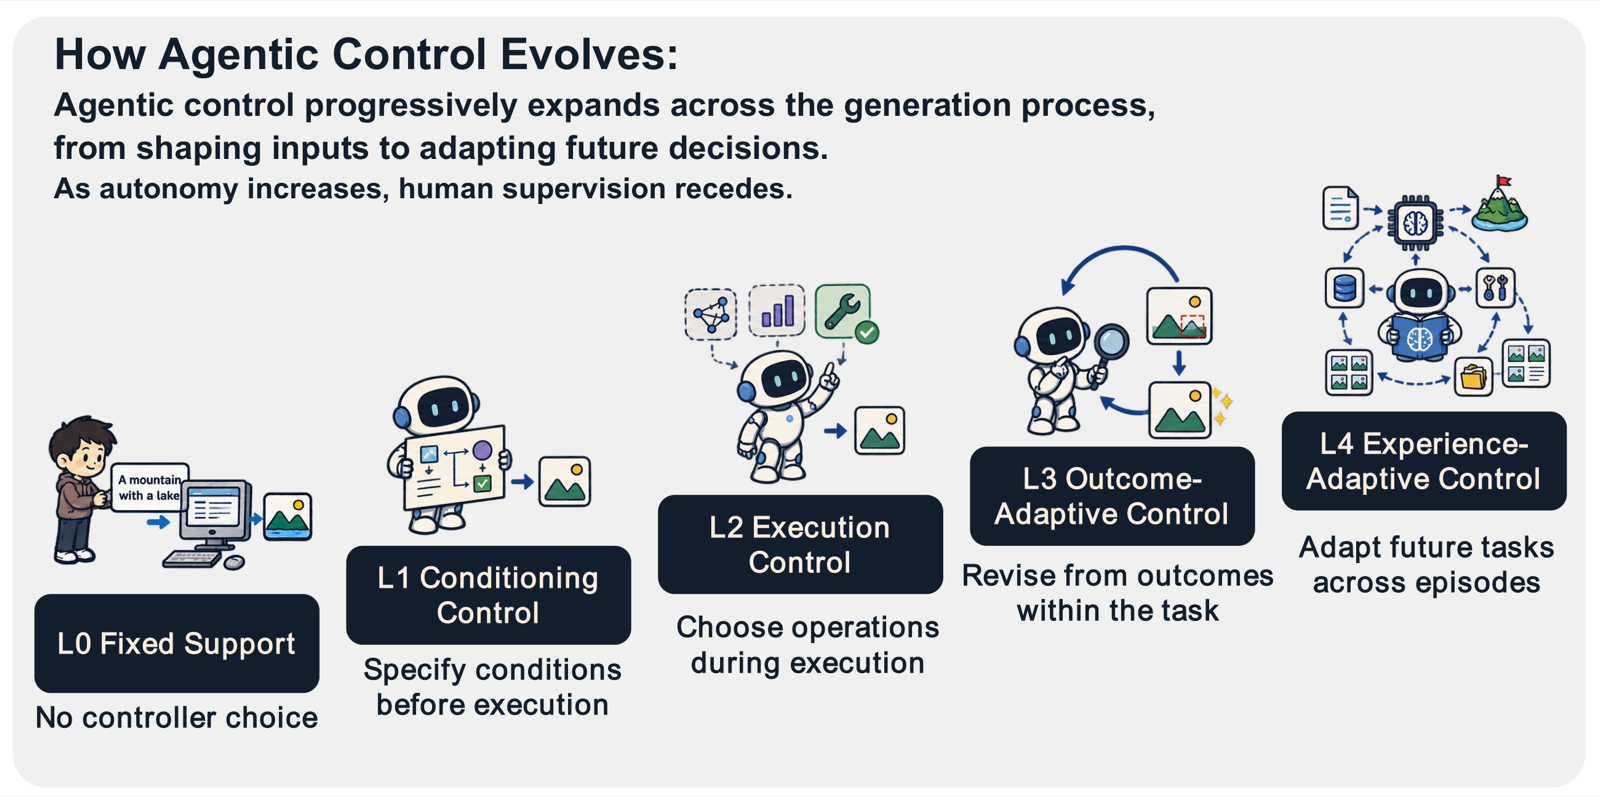
Visual generation is evolving from generative models used through a single invocation into agentic control processes that can plan, select tools, inspect intermediate synthesized outputs, revise failures, and reuse prior experience. In most existing systems, the controller is an LLM or VLM, while visual generation models serve as tools or executors. However, existing work lacks a consistent criterion for determining when a generation system becomes agentic. Planning depth, tool use, multi-role collaboration, and reinforcement learning are often treated as evidence of agenticity, even though none of them necessarily determines which generation decisions the controller can make. We organize the field according to what the controller can directly control in the generation process. At L1 Conditioning Control, the controller prepares the input to a predetermined generator but does not control which visual operation is executed. At L2 Execution Control, it selects and invokes actual generation, editing, rendering, or other content-modifying operations. At L3 Outcome-Adaptive Control, it observes an intermediate outcome and uses that observation to change a subsequent operation within the current task. At L4 Experience-Adaptive Control, it retains experience from completed tasks and uses that experience to change decisions on future tasks. L0 Fixed Support separately denotes generators, editors, evaluators, reward models, benchmarks, and fixed pipelines without a deployed controller that makes generation-level decisions. These levels describe a progressively broader decision-making scope rather than model size, system complexity, output quality, tool or role count, or training method. Applying this framework across image, video, editing, 3D, world, slide, and user-interface generation reveals how controller capabilities have evolved and how their mechanisms are distributed across levels.
@article{huang2026agentic,
  title={Agentic Visual Generation: From Generative Models to Agentic Control},
  author={Huang, Yinming and Tu, Shuyuan and Yan, Xi and Zhan, Jiahao and Yang, Zihan and Xing, Zhen and Zhang, Hui and Zhang, Tiehua and Jiang, Yu-Gang and Wu, Zuxuan},
  journal={arXiv preprint arXiv:2609.06758},
  year={2026}
}
|
|
VA-Judger: Reward Modeling from Human Preference Feedback for Joint Video-Audio Generation
Star
Yinming Huang*, Shuyuan Tu*, Xi Yan, Zihan Yang, Jianhua Han, Hang Xu, Kaihang Pan, Yu-Gang Jiang, Zuxuan Wu
webpage |
abstract |
bibtex |
arXiv |
code |
checkpoints |
dataset |
YouTube |
Bilibili |
量子位 |
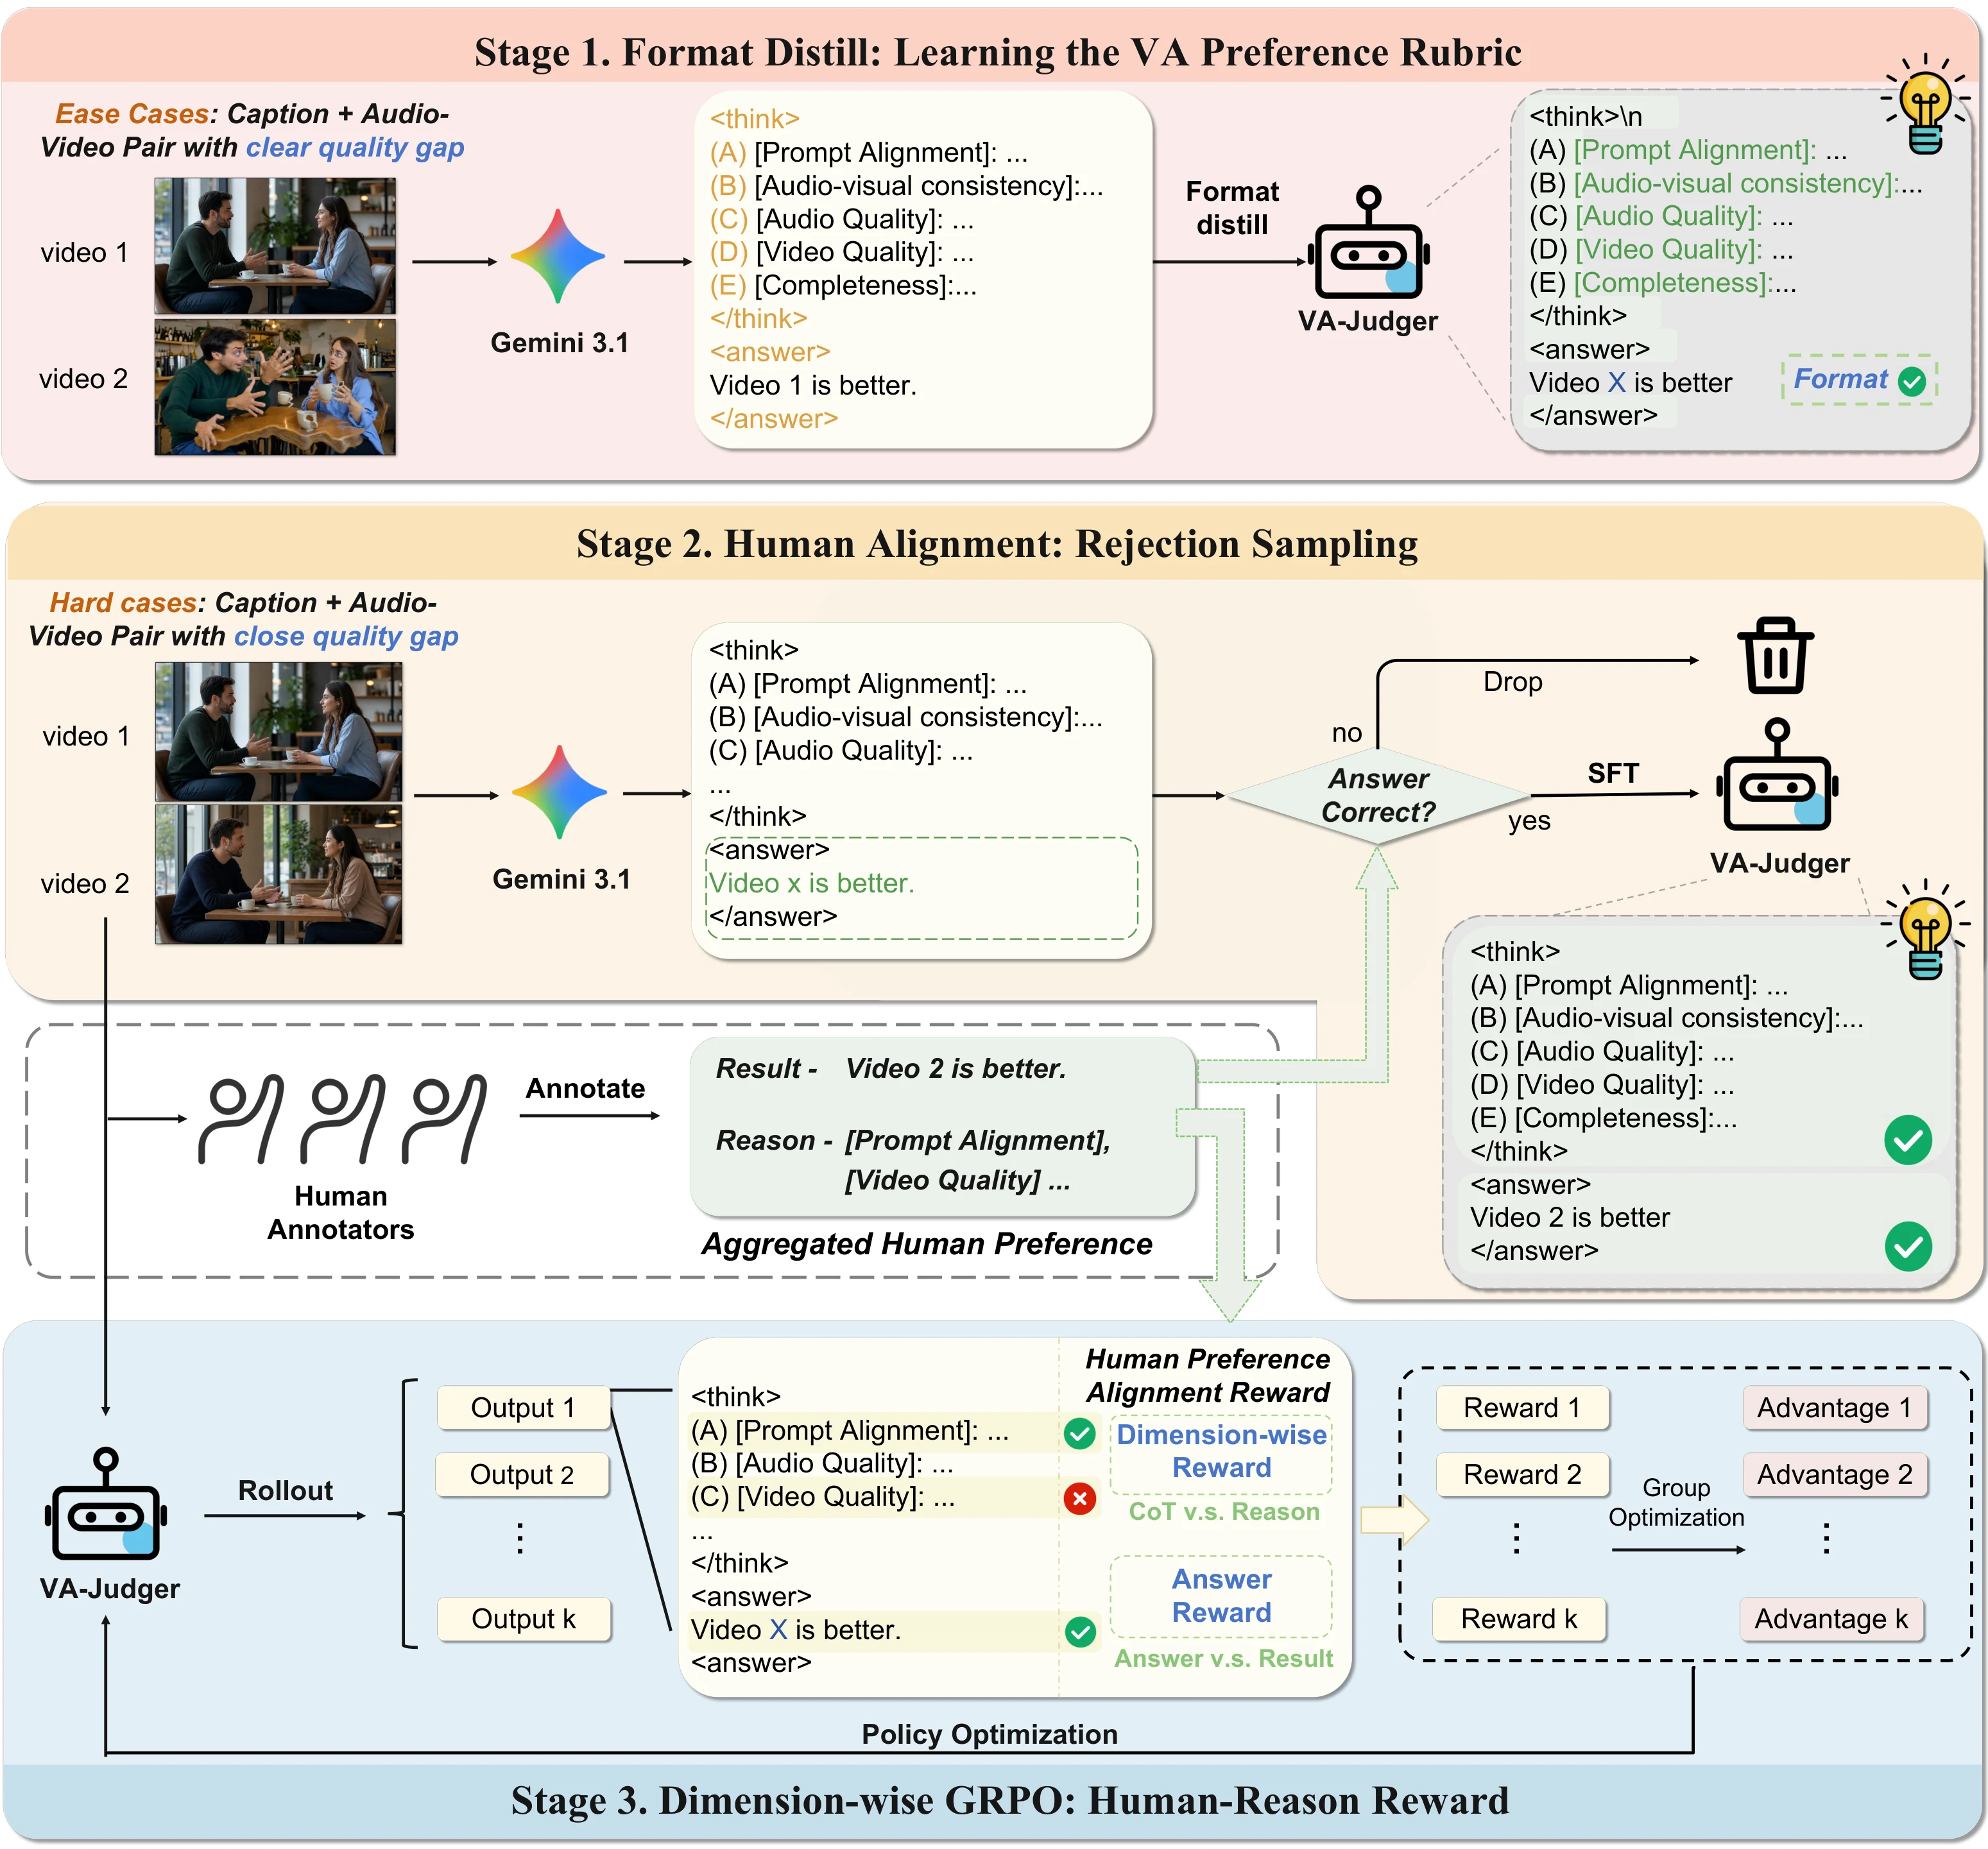
Using reinforcement learning to post-train joint video-audio generation models requires a reward signal. Existing methods construct this reward by combining metrics for individual quality dimensions, including audio quality, visual fidelity, and synchronization. However, these metrics evaluate perceptual dimensions separately and fail to capture the overall semantic and temporal coherence among the text prompt, video, and audio that shapes human preferences. More critically, they are poorly aligned with actual human judgments. Optimizing models against these metrics encourages reward hacking, generating video-audio content that achieves high scores on these metrics yet appears incoherent or unfaithful to human viewers. To address this problem, we first construct VAPref-10K for joint video-audio generation, comprising 9K prompts and 10.3K fine-grained paired comparisons from generation models. We also introduce the VA-Judger-Bench benchmark with both in-domain and out-of-domain model comparisons to evaluate whether reward models truly align with human preferences. We further propose VA-Judger, a chain-of-thought omni-reward model for joint video-audio generation. VA-Judger first learns from pairs with clear quality gaps, then distills format-valid responses for harder near-quality comparisons through rejection sampling verified against human annotations, and finally performs dimension-wise reinforcement learning for denser reward signals. Experiments show that VA-Judger outperforms metric baselines in predicting human preferences on both in-domain and out-of-domain evaluations. Using its human-aligned rewards to post-train an audio-video generation model also improves most automatic metrics and human preference.
@article{huang2026vajudger,
  title={VA-Judger: Reward Modeling from Human Preference Feedback for Joint Video-Audio Generation},
  author={Huang, Yinming and Tu, Shuyuan and Yan, Xi and Yang, Zihan and Han, Jianhua and Xu, Hang and Pan, Kaihang and Jiang, Yu-Gang and Wu, Zuxuan},
  journal={arXiv preprint arXiv:2608.18607},
  year={2026}
}
|
|
[NeurIPS 2026] StableAvatar: Infinite-Length Audio-Driven Avatar Video Generation
Star
Shuyuan Tu, Yueming Pan, Yinming Huang, Xintong Han, Zhen Xing, Qi Dai, Chong Luo, Zuxuan Wu, Yu-Gang Jiang
webpage |
abstract |
bibtex |
arXiv |
code |
YouTube |
Bilibili |
机器之心 |
online demo
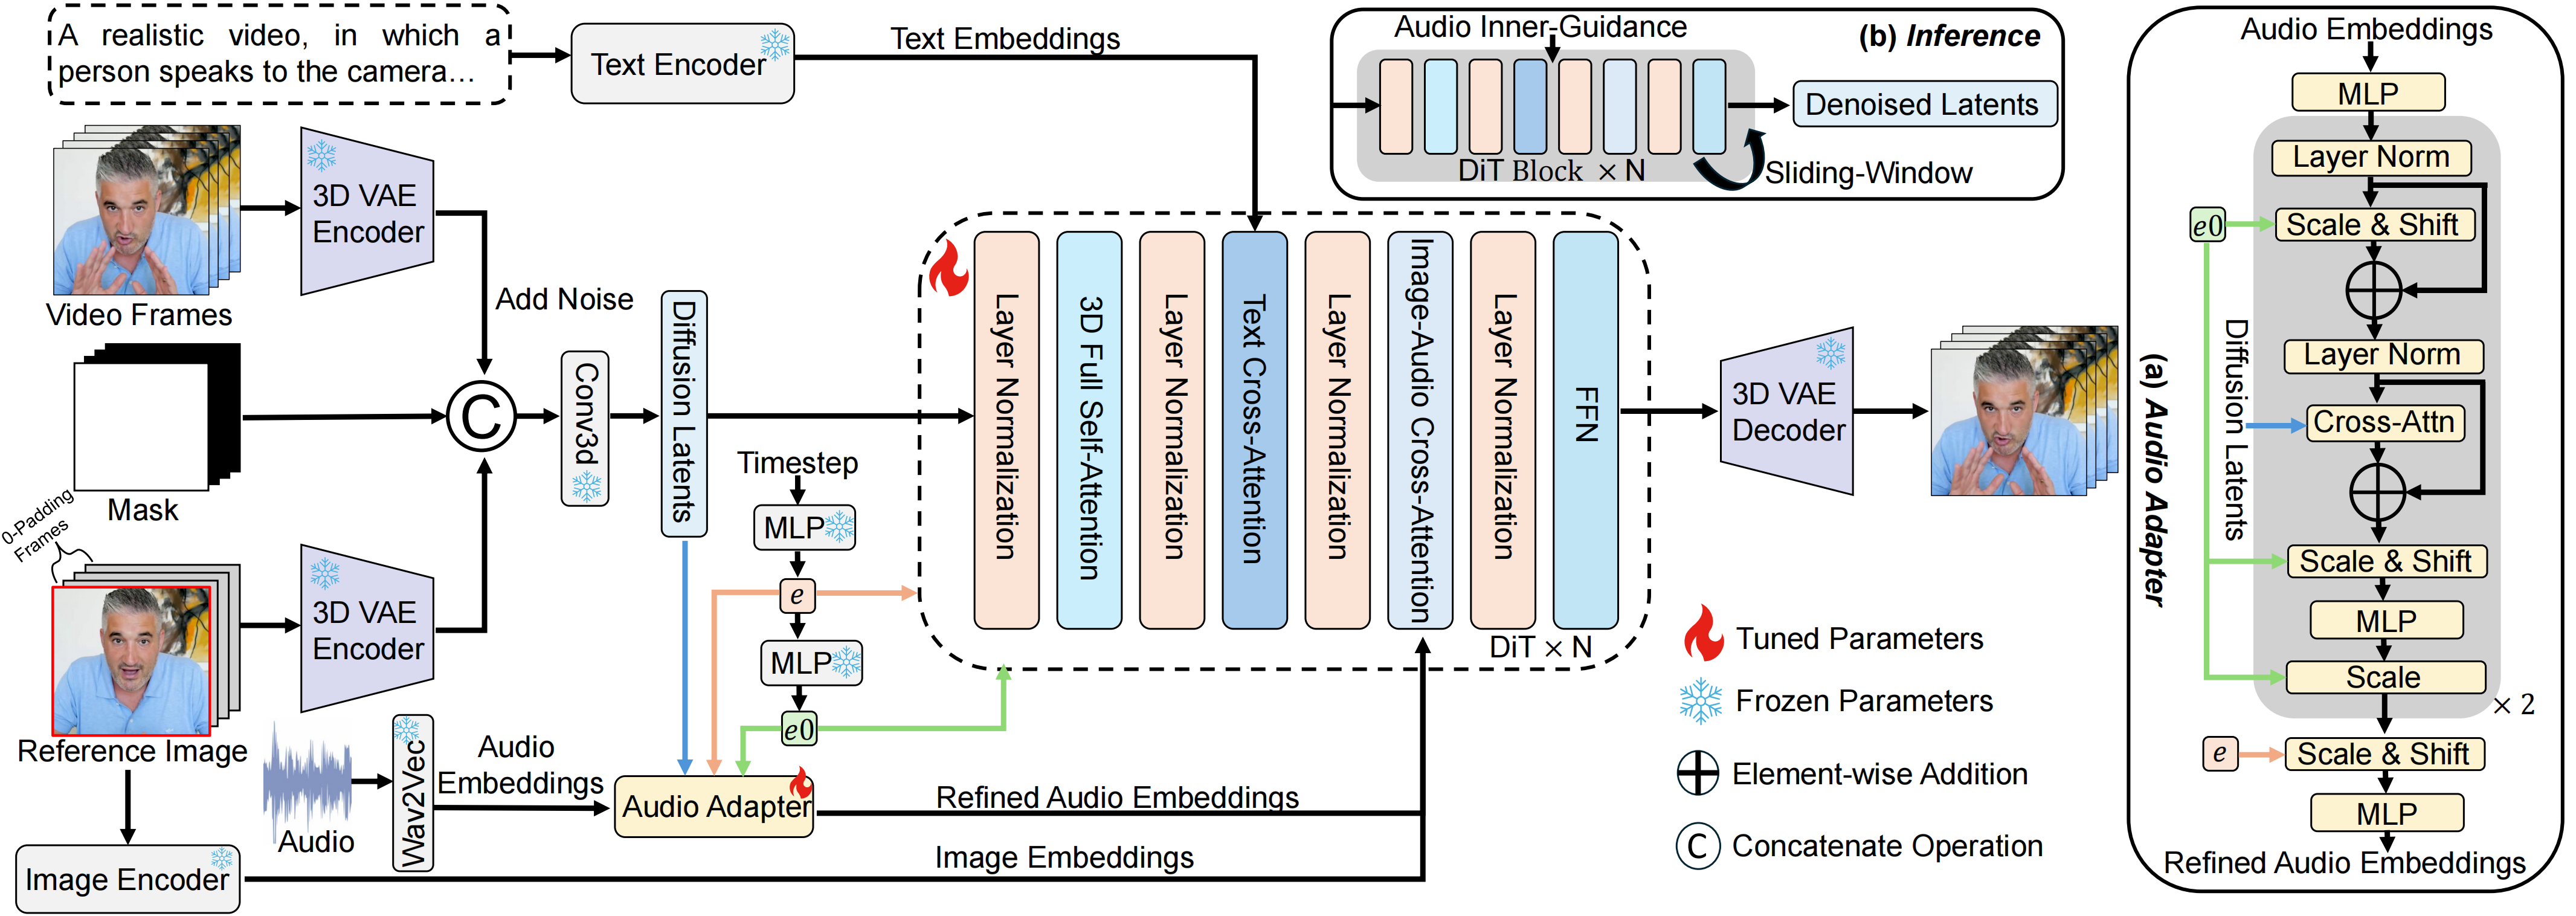
Current diffusion models for audio-driven avatar video generation struggle to synthesize long videos with natural audio synchronization and identity consistency. This paper presents StableAvatar, the first end-to-end video diffusion transformer that synthesizes infinite-length high-quality videos without post-processing. Conditioned on a reference image and audio, StableAvatar integrates tailored training and inference modules to enable infinite-length video generation. We observe that the main reason preventing existing models from generating long videos lies in their audio modeling. They typically rely on third-party off-the-shelf extractors to obtain audio embeddings, which are then directly injected into the diffusion model via cross-attention. Since current diffusion backbones lack any audio-related priors, this approach causes severe latent distribution error accumulation across video clips, leading the latent distribution of subsequent segments to drift away from the optimal distribution gradually. To address this, StableAvatar introduces a novel Time-step-aware Audio Adapter that prevents error accumulation via time-step-aware modulation. During inference, we propose a novel Audio Native Guidance Mechanism to further enhance the audio synchronization by leveraging the diffusion's own evolving joint audio-latent prediction as a dynamic guidance signal. To enhance the smoothness of the infinite-length videos, we introduce a Dynamic Weighted Sliding-window Strategy that fuses latent over time. Experiments on benchmarks show the effectiveness of StableAvatar both qualitatively and quantitatively.
@inproceedings{tu2026stableavatar,
  title={Stableavatar: Infinite-length audio-driven avatar video generation},
  author={Tu, Shuyuan and Pan, Yueming and Huang, Yinming and Han, Xintong and Xing, Zhen and Dai, Qi and Luo, Chong and Wu, Zuxuan and Jiang, Yu-Gang},
  booktitle={Advances in Neural Information Processing Systems},
  year={2026}
}
|
|
[CVPR 2026] FlashPortrait: 6$\times$ Faster Infinite Portrait Animation with Adaptive Latent Prediction
Star
Shuyuan Tu, Yueming Pan, Yinming Huang, Xintong Han, Zhen Xing, Qi Dai, Kai Qiu, Chong Luo, Zuxuan Wu, Yu-Gang Jiang
webpage |
abstract |
bibtex |
arXiv |
code |
YouTube |
Bilibili |
Current diffusion-based acceleration methods for long-portrait animation struggle to ensure identity (ID) consistency. This paper presents FlashPortrait, an end-to-end video diffusion transformer capable of synthesizing ID-preserving, infinite-length videos while achieving up to 6$\times$ acceleration in inference speed. In particular, FlashPortrait begins by computing the identity-agnostic facial expression features with an off-the-shelf extractor. It then introduces a Normalized Facial Expression Block to align facial features with diffusion latents by normalizing them with their respective means and variances, thereby improving identity stability in facial modeling. During inference, FlashPortrait adopts a dynamic sliding-window scheme with weighted blending in overlapping areas, ensuring smooth transitions and ID consistency in long animations. In each context window, based on the latent variation rate at particular timesteps and the derivative magnitude ratio among diffusion layers, FlashPortrait utilizes higher-order latent derivatives at the current timestep to directly predict latents at future timesteps, thereby skipping several denoising steps and achieving 6$\times$ speed acceleration. Experiments on benchmarks show the effectiveness of FlashPortrait both qualitatively and quantitatively.
@article{tu2025flashportrait,
  title={FlashPortrait: 6$\times$ Faster Infinite Portrait Animation with Adaptive Latent Prediction},
  author={Tu, Shuyuan and Pan, Yueming and Huang, Yinming and Han, Xintong and Xing, Zhen and Dai, Qi and Qiu, Kai and Luo, Chong and Wu, Zuxuan},
  journal={arXiv preprint arXiv:2512.16900},
  year={2025}
}
|
|